Rain Li, 李润豪
Hi! I am an MSE Robotics student at the University of Pennsylvania and a recent graduate of the Engineering Science program at the University of Toronto, where I specialized in Robotics Engineering. My research broadly lies at the intersection of robot learning, embodied intelligence, and 3D perception.
During my undergraduate studies, I conducted my thesis research on long-horizon vision-language navigation with hierarchical scene-graph memory and agentic reasoning for robustness with Professor Professor Steven Waslander in Toronto Robotics and AI Lab (TRAIL). Previously, I worked as student researcher at Robot Vision & Learning (RVL) lab with Professor Florian Shkurti on Sparse-view 4D Gaussian Splatting. I also completed a 12-month co-op as Researcher at Noah’s Ark Lab Canada on Autonomous Driving team, focusing 3D reconstruction and generative AI on 3D. In addition, I had multiple summer internships at SenseTime Inc where I worked on NeRF and benchmarking Autonomous Driving algorithms.
Research Interests
My long-term research goal is to develop intelligent robotic systems that can perceive, reason, learn, and act effectively in complex real-world environments. I am particularly interested in:
- Robot Learning & Embodied AI: generalizable robot policies, vision-language-action models, imitation learning, reinforcement learning, and adaptive robot behavior.
- 3D/4D Perception: developing generalizable methods for 3D and 4D scene understanding, generative models, reconstruction, and perception in complex real-world environments.
Research Experiences
Selected Research
AgentVLN: Enhancing Vision Language Navigation with a reasoning Agent based on Explicit memory module
Undergraduate Thesis Completed · Publication in Preparation, 2026
During student researcher at Toronto Robotics and AI Lab
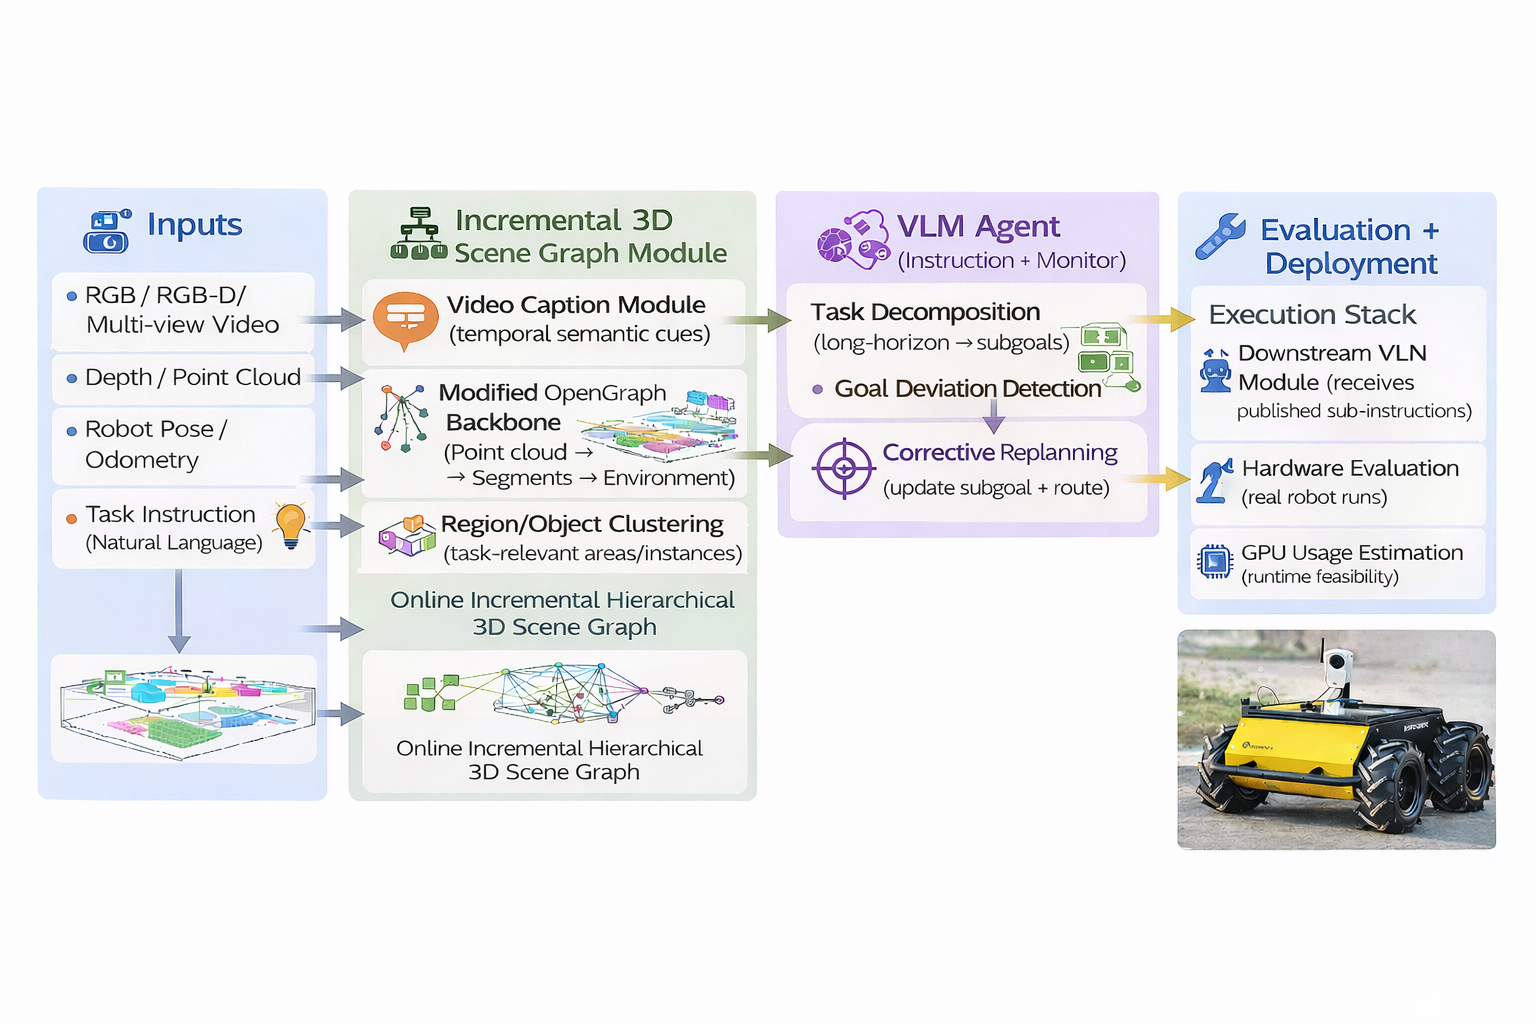
Current vision-language models often lack structural scene understanding and fine-grained details information. These VLNs typically do not maintain an explicit structured memory module to store and organize previously observed information. This limitation becomes especially pronounced in long-horizon tasks. In this work, we propose a novel pipeline that constructs an open-vocabulary,real-time scene-graph from RGBD inputs, video captions and other multimodal inferred information. Our method further clusters scene-graph objects and regions in real-time. Building on this representation, we introduce an LLM-based planning agent that reasons over the continuously updated scene graph to decompose long-horizon instructions, and automatically detect deviation from goal and perform corrective replanning. The agent then publishes more detailed, short-term sub-instructions to a downstream VLN model instead of original long-horizon instructions. We also developed RL-based Husky Locomotion module for downstream of VLN and plan to test in real world scenarios
Sparse-view 4D Gaussian Splatting for robot manipulation scenes
Contribution Completed · Publication in Preparation, 2026
During student researcher at Robot Vision and Learning Lab
Developed a sparse view 4D Gaussian Splatting reconstruction algorithm for use in real-world robot tasks. Conducted real-world experiments that demonstrated improved geometric and photometric quality, along with stronger temporal adaptability, validating the system’s effectiveness beyond simulation. The algorithm cuts the number of input views needed for reconstruction from ∼20 to ∼4. This work will be integrated into the group’s adversarial study on iterative-policy-learning.
STaR: Scalable Task-Conditioned Retrieval for Long-Horizon Multimodal Robot Memory
Accepted by RA-L, 2025
During student researcher at Toronto Robotics and AI Lab
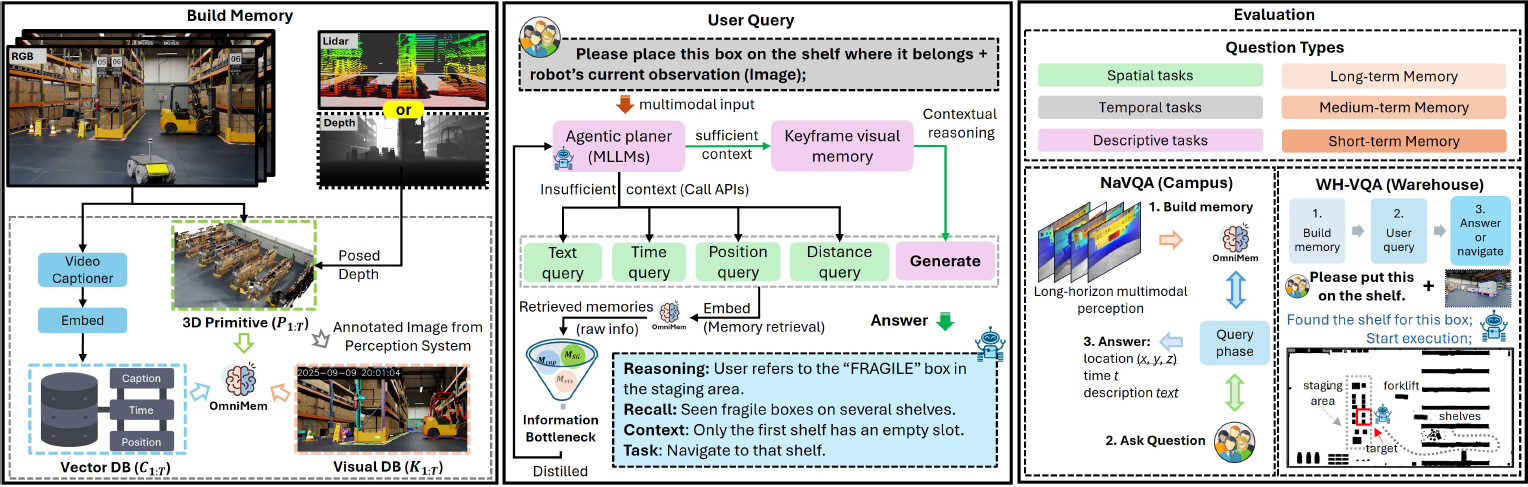
Our framework consists of three stages. 1. Memory construction: the robot records RGB and posed depth data to build a multimodal memory composed of three complementary databases (DB) – video caption, 3D primitive, and visual keyframe – jointly forming OmniMem. 2. User query and reasoning: given text or multimodal queries, an agentic planner (MLLM) retrieves task-relevant memories through an Information Bottleneck, performs contextual reasoning, and outputs structured answers (location, time, or description). 3. Evaluation: We evaluate STaR on both the NaVQA dataset (campus) and the WH-VQA dataset (warehouse), which cover spatial, temporal, and descriptive question types across short-, medium-, and long-term memory settings. The evaluation examines three key capabilities-long horizon cross-modal memory construction, task-conditioned memory retrieval, and contextual reasoning. We also validate the multi-modal query and navigation tasks in a warehouse simulated with Isaac Sim.
Fine-grained information transfer: Details Refinement module for Diffusion based 3D Generation model
Finished during co-op, external constraints prevented publication or release during co-op, 2025
During co-op as a researcher at Noah's Ark Lab
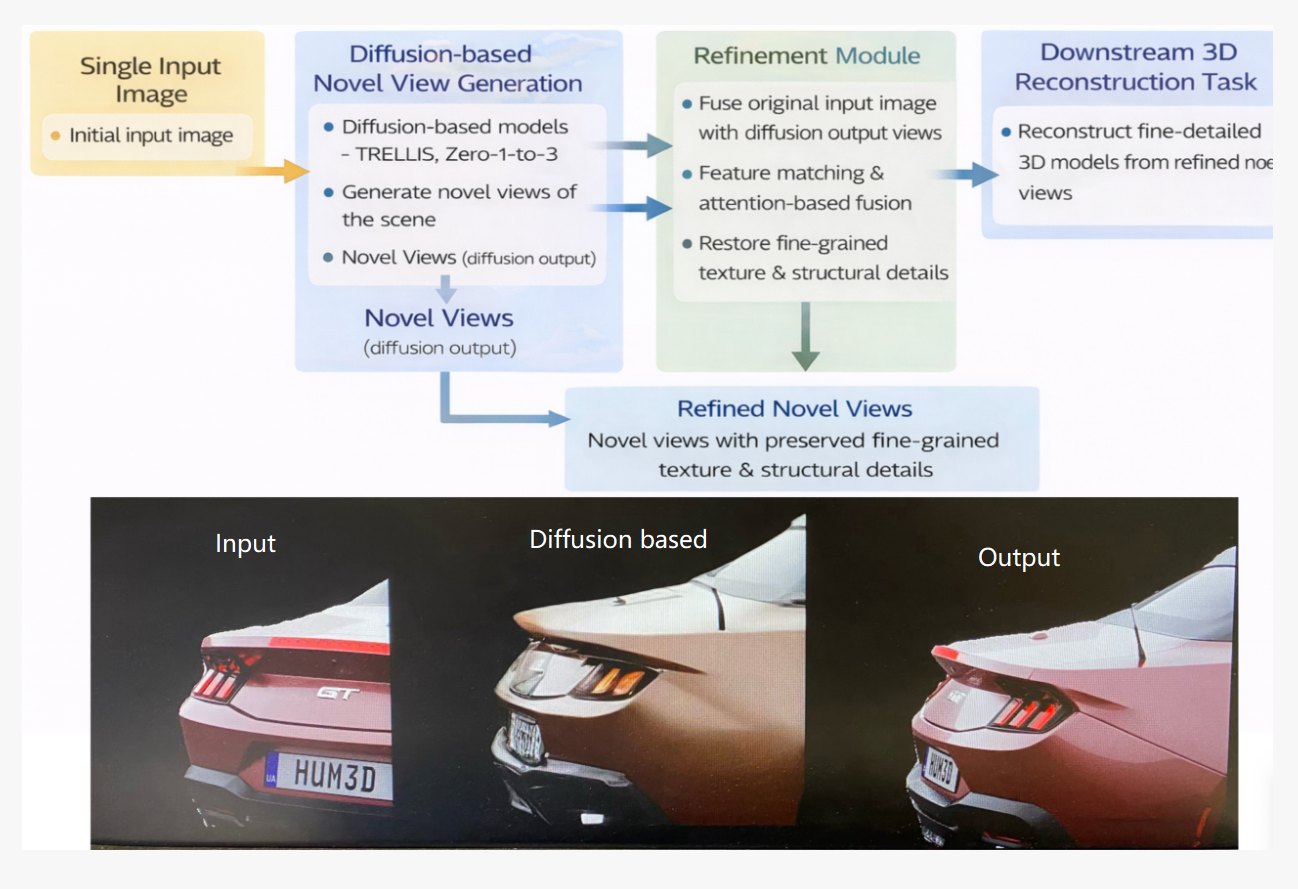
One key limitation of diffusion-based 3D asset generation methods such as TRELLIS and Zero-1-to-3 is their difficulty in preserving fine-grained texture and structural details when synthesizing novel views. To address this, I drew inspiration from optical-flow estimation in Video Frame Interpolation (VFI) and developed a refinement module that transfers fine-detail information from the original input image to diffusion-generated novel-view outputs in feature space. The module integrates feature matching and attention-based fusion, built upon a VFI pipeline to guide detail-preserving correspondence and refinement. As a result, my approach effectively restores high-frequency details in novel views and potentially leads downstream applications such as reconstructing fine-detailed 3D models from a single image.
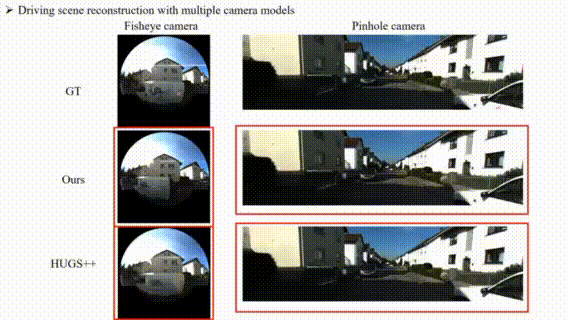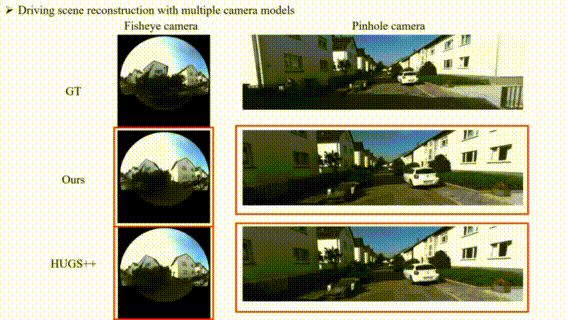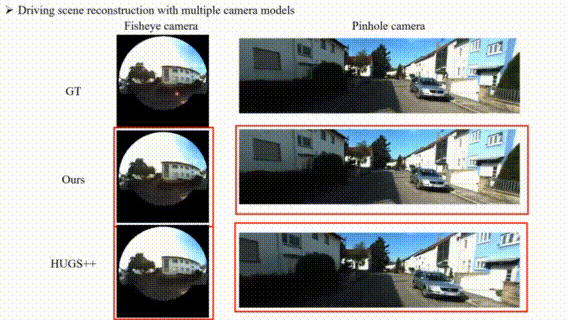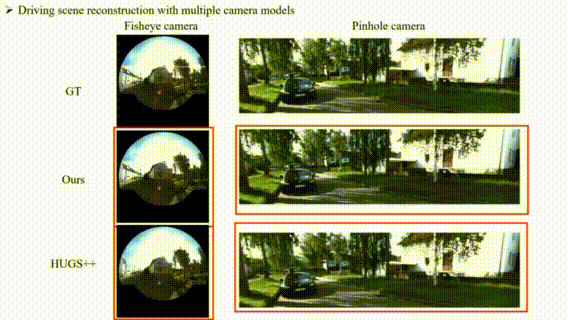
UniGaussian: Driving Scene Reconstruction from Multiple Camera Models via Unified Gaussian Representations
Accepted by 3DV 2026, 2024
During co-op as a researcher at Noah's Ark Lab
In this work, we propose UniGaussian, a novel approach that learns a unified 3D Gaussian representation from multiple camera models for urban scene reconstruction in autonomous driving. Our contributions are two-fold. First, we propose a new differentiable rendering method that distorts 3D Gaussians using a series of affine transformations tailored to fisheye camera models. Besides, our method maintains real-time rendering while ensuring differentiability. Second, built on the differentiable rendering method, we design a new framework that learns a unified Gaussian representation from multiple camera models. By applying affine transformations to adapt different camera models and regularizing the shared Gaussians with supervision from different modalities, our framework learns a unified 3D Gaussian representation with input data from multiple sources and achieves holistic driving scene understanding. As a result, our approach models multiple sensors (pinhole and fisheye cameras) and modalities (depth, semantic, normal and LiDAR point clouds). Our experiments show that our method achieves superior rendering quality and fast rendering speed for driving scene simulation.
3D Gaussian Reconstruction in various lighting condition for autonomous driving scene
Research project that integrated to group's autonomous driving scene reconstruction pipeline, 2024
During co-op as a researcher at Noah's Ark Lab
Standard 3DGS fails under inconsistent illumination, I contributed to the research work on enabling reconstruction under various lighting conditions. This work was developed based on Relightable 3DGS work and upgrated by incorporating physical lighting models, BRDF decomposition, and material-segmentation priors for guidance of lighting estimation. Our method extends attribute of each gaussian point with local and global light attributes. When optimizing the model, this decouples local light incidents and global incidents. The model enables geometry optimization shared across lighting conditions while optimizing the global illumination environment. The result PSNR and other metrics got improved and this work integrated into group’s work in autonomous driving reconstruction pipeline.
Enhanced NeRF on heavy occluded conditions for crops
Research project for Intelligent Crop Breeding project, 2023
During internship as a researcher at SenseTime Inc.
Based on the benchmarked classical structure-from-motion pipeline and neural radiance fields (NeRF) variants for this field, We strived to devise an enhanced NeRF, one that incorporated cross-view feature correlation and geometric priors on leaves and fruits to achieve high-fidelity reconstruction in real world experiments for heavy occluded conditions. In doing so, the resulting 3D models successfully supported downstream applications in phenotype estimation and crop-quality prediction accomplishments in real world scenarios.